Benchmarking Reaction Energies across Basis Sets
Run reaction-energy workflow with multiple basis sets and compare the resulting trends in a reproducible PLAMS benchmark.
Initial Imports
import sys
import multiprocessing
from scm.base import ChemicalSystem
from scm.inputs import ADF, AMS
from scm.plams import (
    JobRunner,
    config,
    AMSJob,
    JobAnalysis,
    jobs_in_directory,
    view,
    plot_image_grid,
)
import numpy as np
Set Up Job Runner
Set up job runner, running as many jobs as possible in parallel.
config.default_jobrunner = JobRunner(parallel=True, maxjobs=multiprocessing.cpu_count())
config.job.runscript.nproc = 1
Set Up Molecules
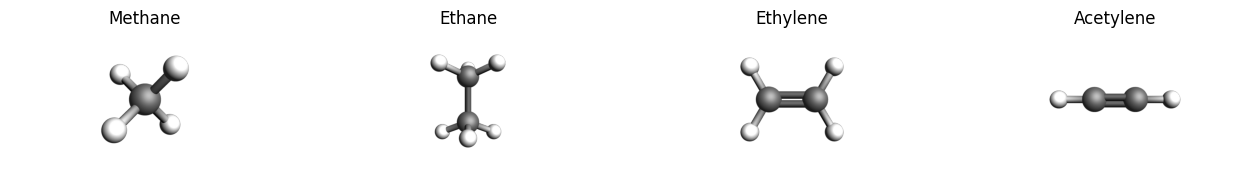
Create the molecules we want to use in our benchmark from SMILES.
# The molecules we want to use in our benchmark:
mol_smiles = {"Methane": "C", "Ethane": "C-C", "Ethylene": "C=C", "Acetylene": "C#C"}
molecules = {}
for name, smiles in mol_smiles.items():
    # Compute 10 conformers, optimize with UFF and pick the lowest in energy.
    system = ChemicalSystem.from_smiles(smiles, optimize_with_uff=True, num_trial_conformers=10)
    # The System block's Symmetrize option is not part of the typed input model,
    # so symmetry cleanup of the geometry is now a ChemicalSystem operation.
    system.symmetrize()
    molecules[name] = system

plot_image_grid({k: view(v, direction="along_pca3") for k, v in molecules.items()}, rows=1);
Initialize Calculation Settings
Set up the settings which are common across jobs. The basis type is added later for each job.
common_settings = AMS(Task="SinglePoint")
common_settings.Engine = ADF()
common_settings.Engine.Basis.Core = "None"
basis = ["QZ4P", "TZ2P", "TZP", "DZP", "DZ", "SZ"]
reference_basis = "QZ4P"
Run Calculations
results = {}
jobs = []
for bas in basis:
    for name, molecule in molecules.items():
        with jobs_in_directory(name):
            settings = common_settings.copy()
            settings.Engine.Basis.Type = bas
            job = AMSJob(name=f"{name}_{bas}", molecule=molecule, settings=settings)
            jobs.append(job)
            results[(name, bas)] = job.run()

for job in jobs:
    job.ok()
[19.10|12:14:47] JOB Methane_QZ4P STARTED
[19.10|12:14:47] JOB Ethane_QZ4P STARTED
[19.10|12:14:47] JOB Ethylene_QZ4P STARTED
[19.10|12:14:47] JOB Acetylene_QZ4P STARTED
[19.10|12:14:47] JOB Methane_TZ2P STARTED
[19.10|12:14:47] JOB Ethane_TZ2P STARTED
[19.10|12:14:47] JOB Ethylene_TZ2P STARTED
[19.10|12:14:47] JOB Methane_QZ4P RUNNING
[19.10|12:14:47] JOB Ethane_QZ4P RUNNING
[19.10|12:14:48] JOB Acetylene_TZ2P STARTED
... output trimmed ....
[19.10|12:14:56] JOB Ethylene_TZP SUCCESSFUL
[19.10|12:14:56] JOB Acetylene_DZ SUCCESSFUL
[19.10|12:14:56] JOB Ethylene_SZ FINISHED
[19.10|12:14:56] JOB Ethylene_SZ SUCCESSFUL
[19.10|12:14:56] JOB Ethane_SZ FINISHED
[19.10|12:14:56] JOB Ethane_SZ SUCCESSFUL
[19.10|12:14:56] JOB Ethylene_DZ FINISHED
[19.10|12:14:56] JOB Ethylene_DZ SUCCESSFUL
[19.10|12:14:56] JOB Acetylene_DZP FINISHED
[19.10|12:14:56] JOB Acetylene_DZP SUCCESSFUL
Results
Extract the energy from each calculation. Calculate the average absolute error in bond energy per atom for each basis set.
import pandas as pd

results = []
for job in jobs:
    mol = job.results.get_main_system()
    results.append(
        {
            "Formula": mol.formula(),
            "Basis": job.settings.input.Engine.Basis.Type,
            "NAtoms": len(mol),
            "Energy": job.results.get_energy(unit="kcal/mol"),
        }
    )

results_df = pd.DataFrame(results)
results_df
Formula | Basis | NAtoms | Energy | |
|---|---|---|---|---|
0 | CH4 | QZ4P | 5 | -572.626762 |
1 | C2H6 | QZ4P | 8 | -973.019469 |
2 | C2H4 | QZ4P | 6 | -770.413350 |
3 | C2H2 | QZ4P | 4 | -556.759051 |
4 | CH4 | TZ2P | 5 | -572.110159 |
5 | C2H6 | TZ2P | 8 | -971.882017 |
6 | C2H4 | TZ2P | 6 | -769.432902 |
7 | C2H2 | TZ2P | 4 | -555.667288 |
8 | CH4 | TZP | 5 | -571.044897 |
9 | C2H6 | TZP | 8 | -970.075887 |
10 | C2H4 | TZP | 6 | -767.327516 |
11 | C2H2 | TZP | 4 | -552.956282 |
12 | CH4 | DZP | 5 | -569.119016 |
13 | C2H6 | DZP | 8 | -966.091643 |
14 | C2H4 | DZP | 6 | -764.413297 |
15 | C2H2 | DZP | 4 | -550.646178 |
16 | CH4 | DZ | 5 | -560.934431 |
17 | C2H6 | DZ | 8 | -951.166693 |
18 | C2H4 | DZ | 6 | -750.174509 |
19 | C2H2 | DZ | 4 | -537.100799 |
20 | CH4 | SZ | 5 | -723.550123 |
21 | C2H6 | SZ | 8 | -1216.914229 |
22 | C2H4 | SZ | 6 | -934.655819 |
23 | C2H2 | SZ | 4 | -647.502978 |
ref_results_df = results_df[results_df["Basis"] == "QZ4P"]
comp_results_df = results_df[results_df["Basis"] != "QZ4P"]
comp_results_df = comp_results_df.merge(ref_results_df, on="Formula", suffixes=["", " (Ref)"])
comp_results_df["Average Error"] = (
    abs(comp_results_df["Energy"] - comp_results_df["Energy (Ref)"]) / comp_results_df["NAtoms"]
)
comp_results_df
Formula | Basis | NAtoms | Energy | Basis (Ref) | NAtoms (Ref) | Energy (Ref) | Average Error | |
|---|---|---|---|---|---|---|---|---|
0 | CH4 | TZ2P | 5 | -572.110159 | QZ4P | 5 | -572.626762 | 0.103321 |
1 | CH4 | TZP | 5 | -571.044897 | QZ4P | 5 | -572.626762 | 0.316373 |
2 | CH4 | DZP | 5 | -569.119016 | QZ4P | 5 | -572.626762 | 0.701549 |
3 | CH4 | DZ | 5 | -560.934431 | QZ4P | 5 | -572.626762 | 2.338466 |
4 | CH4 | SZ | 5 | -723.550123 | QZ4P | 5 | -572.626762 | 30.184672 |
5 | C2H6 | TZ2P | 8 | -971.882017 | QZ4P | 8 | -973.019469 | 0.142182 |
6 | C2H6 | TZP | 8 | -970.075887 | QZ4P | 8 | -973.019469 | 0.367948 |
7 | C2H6 | DZP | 8 | -966.091643 | QZ4P | 8 | -973.019469 | 0.865978 |
8 | C2H6 | DZ | 8 | -951.166693 | QZ4P | 8 | -973.019469 | 2.731597 |
9 | C2H6 | SZ | 8 | -1216.914229 | QZ4P | 8 | -973.019469 | 30.486845 |
10 | C2H4 | TZ2P | 6 | -769.432902 | QZ4P | 6 | -770.413350 | 0.163408 |
11 | C2H4 | TZP | 6 | -767.327516 | QZ4P | 6 | -770.413350 | 0.514306 |
12 | C2H4 | DZP | 6 | -764.413297 | QZ4P | 6 | -770.413350 | 1.000009 |
13 | C2H4 | DZ | 6 | -750.174509 | QZ4P | 6 | -770.413350 | 3.373140 |
14 | C2H4 | SZ | 6 | -934.655819 | QZ4P | 6 | -770.413350 | 27.373745 |
15 | C2H2 | TZ2P | 4 | -555.667288 | QZ4P | 4 | -556.759051 | 0.272941 |
16 | C2H2 | TZP | 4 | -552.956282 | QZ4P | 4 | -556.759051 | 0.950692 |
17 | C2H2 | DZP | 4 | -550.646178 | QZ4P | 4 | -556.759051 | 1.528218 |
18 | C2H2 | DZ | 4 | -537.100799 | QZ4P | 4 | -556.759051 | 4.914563 |
19 | C2H2 | SZ | 4 | -647.502978 | QZ4P | 4 | -556.759051 | 22.685982 |
benchmark_results_df = comp_results_df.groupby("Basis", as_index=False)["Average Error"].mean()
benchmark_results_df.rename(columns={"Average Error": "MAE [kcal/mol]"}, inplace=True)
benchmark_results_df.sort_values(by="MAE [kcal/mol]", inplace=True, ignore_index=True)
benchmark_results_df
Basis | MAE [kcal/mol] | |
|---|---|---|
0 | TZ2P | 0.170463 |
1 | TZP | 0.537330 |
2 | DZP | 1.023939 |
3 | DZ | 3.339442 |
4 | SZ | 27.682811 |
See also
Python Script
#!/usr/bin/env python
# coding: utf-8

# ## Initial Imports

import sys
import multiprocessing
from scm.base import ChemicalSystem
from scm.inputs import ADF, AMS
from scm.plams import (
    JobRunner,
    config,
    AMSJob,
    JobAnalysis,
    jobs_in_directory,
    view,
    plot_image_grid,
)
import numpy as np


# ## Set Up Job Runner
# Set up job runner, running as many jobs as possible in parallel.

config.default_jobrunner = JobRunner(parallel=True, maxjobs=multiprocessing.cpu_count())
config.job.runscript.nproc = 1


# ## Set Up Molecules
# Create the molecules we want to use in our benchmark from SMILES.

# The molecules we want to use in our benchmark:
mol_smiles = {"Methane": "C", "Ethane": "C-C", "Ethylene": "C=C", "Acetylene": "C#C"}
molecules = {}
for name, smiles in mol_smiles.items():
    # Compute 10 conformers, optimize with UFF and pick the lowest in energy.
    system = ChemicalSystem.from_smiles(smiles, optimize_with_uff=True, num_trial_conformers=10)
    # The System block's Symmetrize option is not part of the typed input model,
    # so symmetry cleanup of the geometry is now a ChemicalSystem operation.
    system.symmetrize()
    molecules[name] = system

plot_image_grid({k: view(v, direction="along_pca3") for k, v in molecules.items()}, rows=1, save_path="picture1.png");


# ## Initialize Calculation Settings
# Set up the settings which are common across jobs. The basis type is added later for each job.

common_settings = AMS(Task="SinglePoint")
common_settings.Engine = ADF()
common_settings.Engine.Basis.Core = "None"


basis = ["QZ4P", "TZ2P", "TZP", "DZP", "DZ", "SZ"]
reference_basis = "QZ4P"


# ## Run Calculations

results = {}
jobs = []
for bas in basis:
    for name, molecule in molecules.items():
        with jobs_in_directory(name):
            settings = common_settings.copy()
            settings.Engine.Basis.Type = bas
            job = AMSJob(name=f"{name}_{bas}", molecule=molecule, settings=settings)
            jobs.append(job)
            results[(name, bas)] = job.run()

for job in jobs:
    job.ok()


# ## Results
# Extract the energy from each calculation. Calculate the average absolute error in bond energy per atom for each basis set.

import pandas as pd

results = []
for job in jobs:
    mol = job.results.get_main_system()
    results.append(
        {
            "Formula": mol.formula(),
            "Basis": job.settings.input.Engine.Basis.Type,
            "NAtoms": len(mol),
            "Energy": job.results.get_energy(unit="kcal/mol"),
        }
    )

results_df = pd.DataFrame(results)
print(results_df)


ref_results_df = results_df[results_df["Basis"] == "QZ4P"]
comp_results_df = results_df[results_df["Basis"] != "QZ4P"]
comp_results_df = comp_results_df.merge(ref_results_df, on="Formula", suffixes=["", " (Ref)"])
comp_results_df["Average Error"] = (
    abs(comp_results_df["Energy"] - comp_results_df["Energy (Ref)"]) / comp_results_df["NAtoms"]
)
print(comp_results_df)


benchmark_results_df = comp_results_df.groupby("Basis", as_index=False)["Average Error"].mean()
benchmark_results_df.rename(columns={"Average Error": "MAE [kcal/mol]"}, inplace=True)
benchmark_results_df.sort_values(by="MAE [kcal/mol]", inplace=True, ignore_index=True)
print(benchmark_results_df)